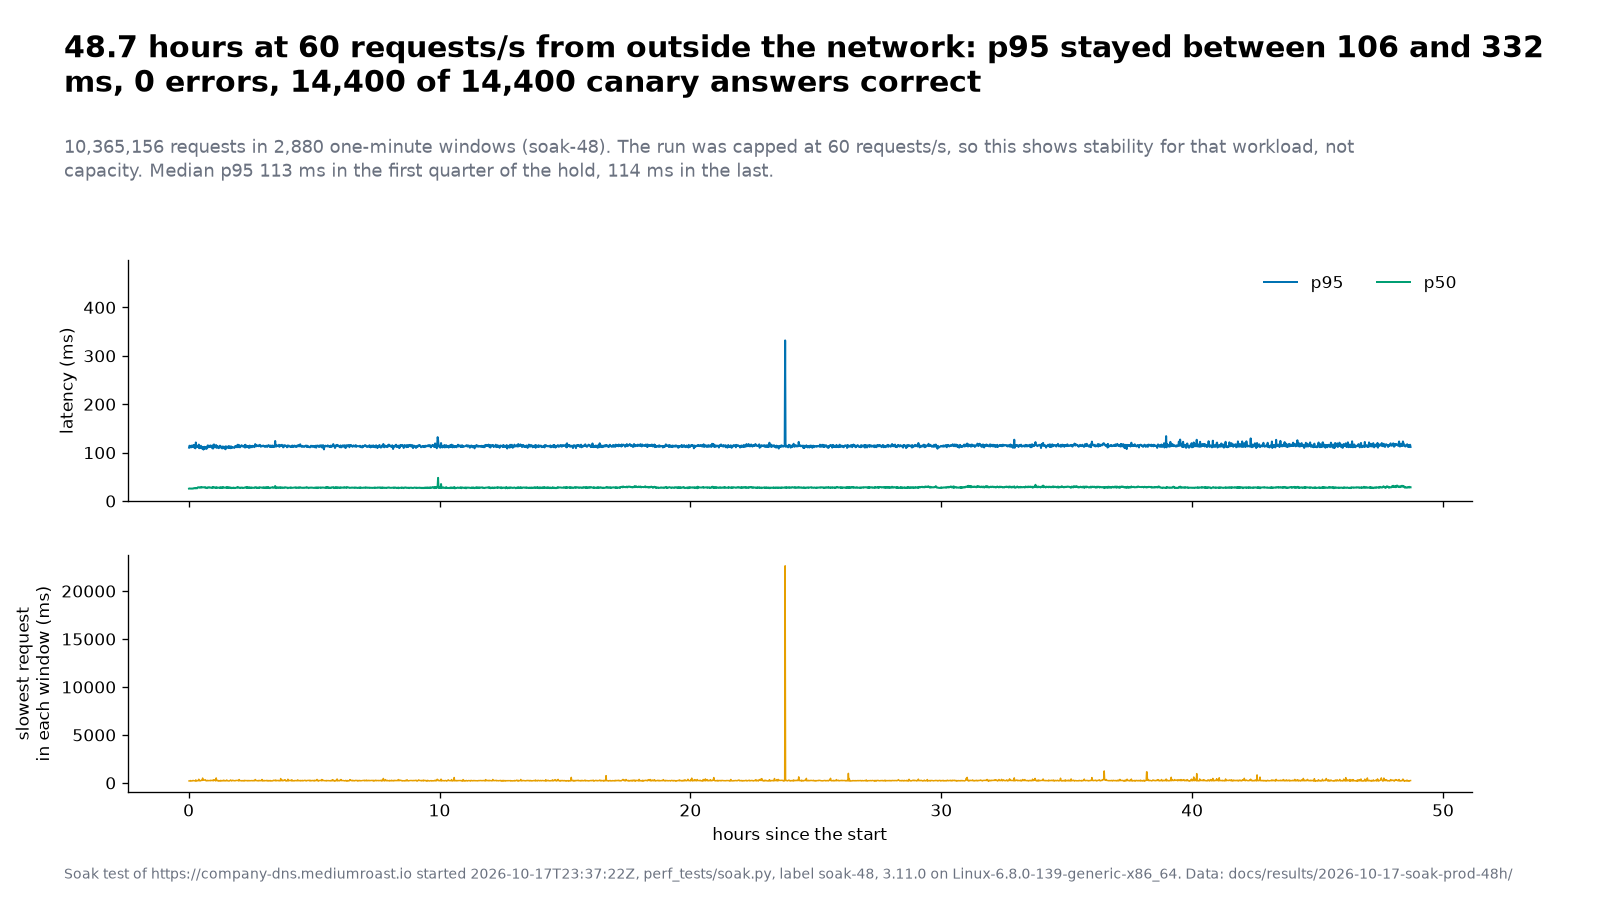
perf_tests/soak.py run by a remote tester from outside the network against production (https://company-dns.mediumroast.io, served by V4 since 17 October) at a steady 60 requests/s with no credentials (guide: docs/soak-prod-48h.md). Analysis: docs/performance-report.md, section 3b; picture: ../2026-10-20/s1-soak-48h.png.
summary.md: the run’s own summary (verdict PASS).windows.csv: one row per one-minute window (2,880 rows). meta.json: the run’s settings and the tester’s platform.windows.jsonl (the same rows as JSON) and canaries.jsonl (14,400 known-answer checks, all correct); the maintainers keep them.watch-v3/watch.csv: the cluster-side watcher, which did not watch V4. It ran for 2 hours 17 minutes from 23:11 UTC on 17 October (just after the cutover) and then stopped (it was not run in tmux). Its label selector was the fixed app.kubernetes.io/name=company-dns, which in the production namespace is V3’s four pods, so it recorded V3 idle (0.01 to 0.03 cores, up to 69 MiB, no restarts) and not one V4 pod. The selector is now an option (pod_watch.py --selector). There is no cluster-side record of V4 for this soak. One read-only look afterwards (20 October, after the soak ended) found all 20 V4 pods the age of the deployment (2 days 4 hours) with 0 restarts and 160 to 172 MiB of memory each; it is a snapshot, not a record (performance report, section 3b).